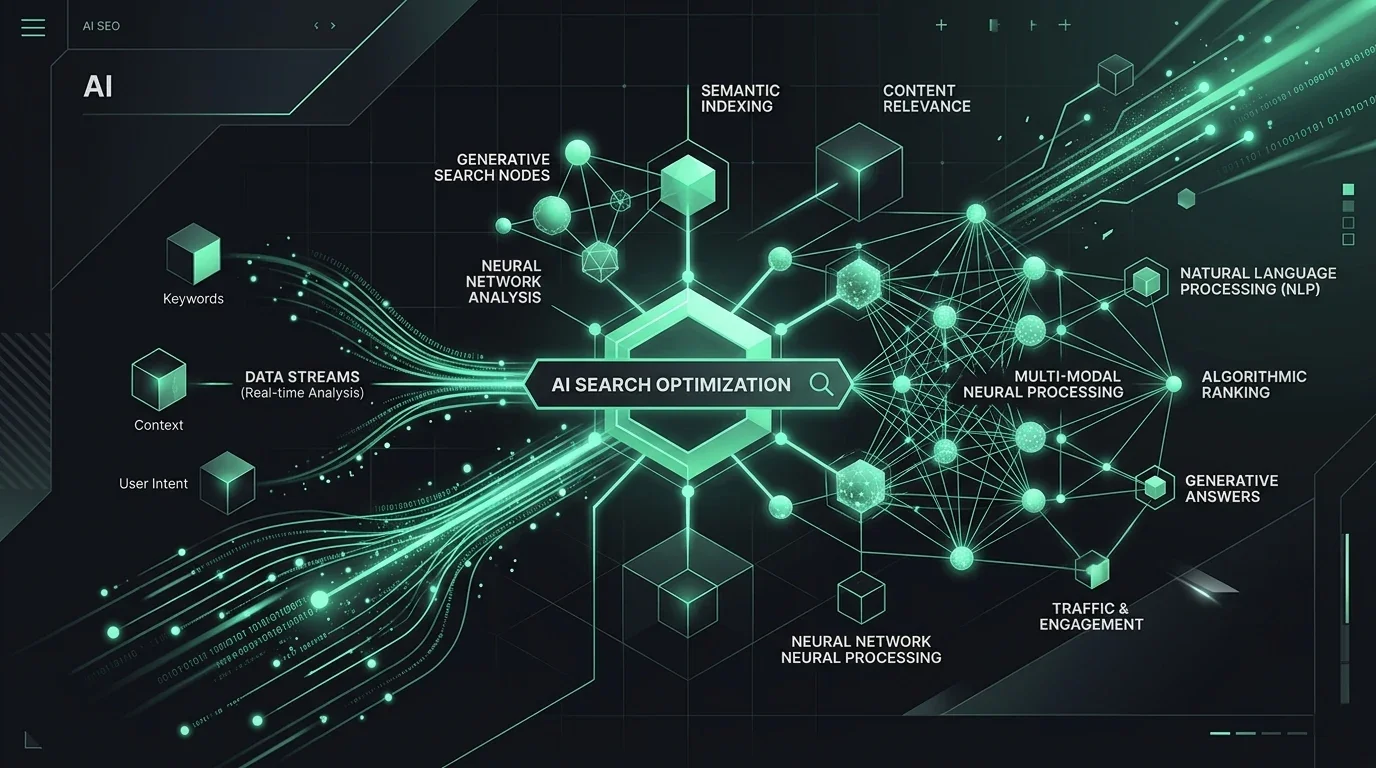
The Key Takeaway: Context window marketing is the strategic discipline of structuring company data, narrative assets, and technical proof points so generative engines prioritize your brand within token constraints. By dominating retrieval-augmented context windows, brands secure top recommendations inside ChatGPT, Claude, and Perplexity workflows.
The Shift from PageRank to Context Injection
Traditional search marketing obsessed over positioning URLs on static results pages. In generative search, search engines no longer return blue links to human clickers; an orchestrator fetches high-relevance chunks, compiles them into a context window, and synthesizes a direct answer. If your product does not survive this compression step, you do not exist to the buyer.
Generative models operate under bounded token budgets during multi-hop reasoning. When an enterprise evaluator asks an AI agent to build a vendor shortlist, the model compresses dozens of sources into a distilled context payload. Survival in this pipeline requires precise semantic density.
- Information Density over Word Count: Large language models discard verbose filler during semantic chunking. High-density technical specifications, benchmark scores, and concrete outcomes survive retrieval filters.
- Relational Entity Anchoring: Your brand must be consistently linked to categorical problems, competitor trade-offs, and verified integration ecosystems across third-party documentation.
- Structured Extraction Readiness: Content structured as clear tabular comparisons, unambiguous pricing frameworks, and definitive architectural statements takes priority during synthesis.
Operationalizing Semantic Density
Founders often wonder why their multi-million dollar content library yields zero recommendations in AI conversational engines. The answer is semantic dilution: thousands of blog posts filled with corporate fluff that search crawlers parse as low-confidence noise. Through our Agentic Embed engagements, we audit client footprint vectors and rebuild digital distribution to lock your product into these dynamic evaluation pipelines.
Architecting for Retrieval-Augmented Recommendation
When buyer agents trigger retrieval-augmented generation (RAG) loops, vector embeddings evaluate candidate documents based on cosine similarity and authority weighting. Winning this step demands deliberate infrastructure rather than casual public relations.
To engineer context dominance, growth leaders must deploy a programmatic footprint across the knowledge sources that generative crawlers trust implicitly.
- Vector Proximity Seeding: Seed public discourse in primary documentation hubs, open GitHub discussions, technical registries, and industry forums where evaluation crawlers source validation datasets.
- Neutral Comparison Footprints: LLMs distrust unverified self-promotional copy. They heavily weight balanced analyses that articulate specific trade-offs, ideal customer profiles, and technical boundary conditions.
- Machine-Readable Consensus: When an AI searches for peer validation, it clusters community sentiment across Reddit, Hacker News, and specialized Slack archives. Uniform semantic sentiment directly informs recommendation weighting.
Transforming Growth Engineering
Winning enterprise pipeline in an autonomous world requires moving past obsolete MQL playbooks. B2B software decisions are increasingly mediated by synthetic research swarms that parse your entire digital footprint in seconds. We help engineering-led founders deploy our Agentic Embed system to build durable, real-time citation pipelines that consistently win generative shortlists.