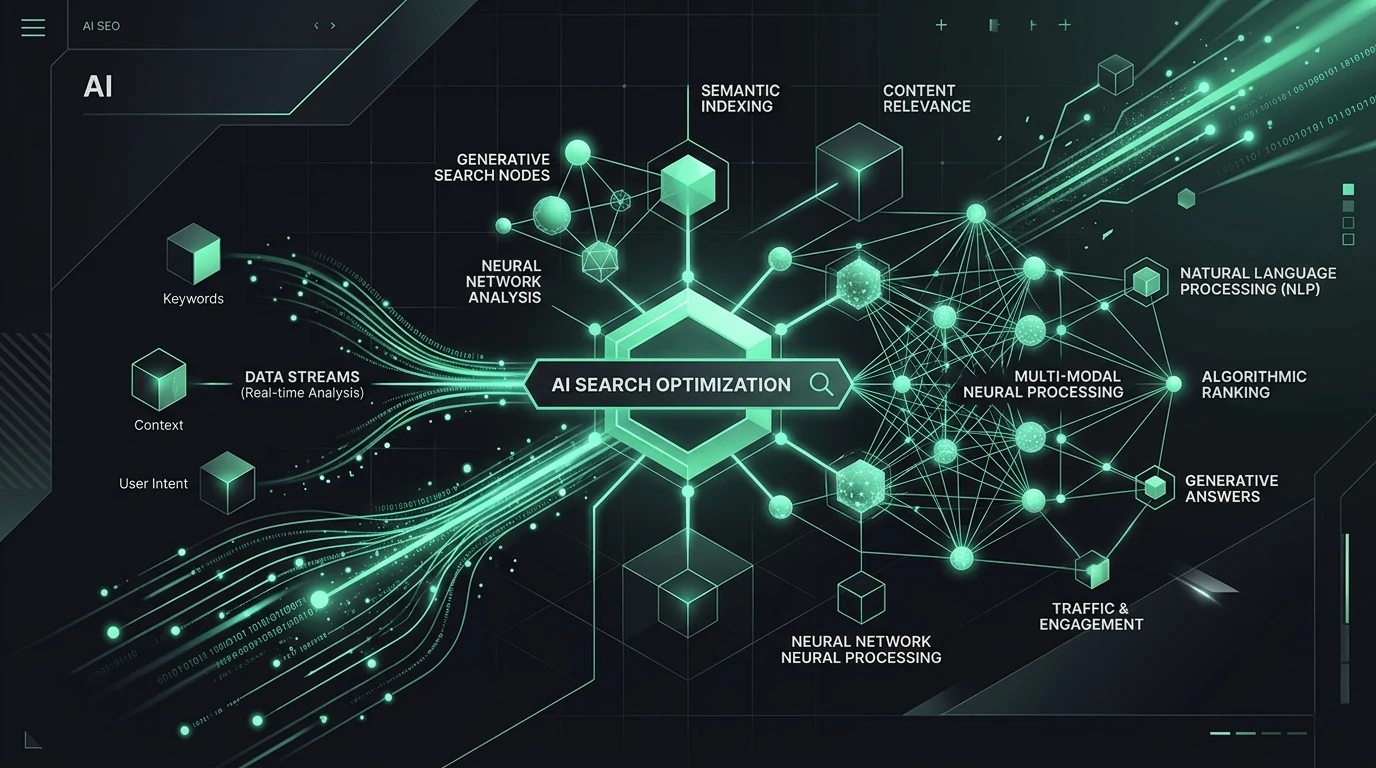
The Key Takeaway: Answer Engine Optimization (AEO) requires structuring web pages for Retrieval-Augmented Generation (RAG) extractors rather than keyword algorithms. To dominate AI search citations in 2026, websites must deliver factual Answer-First capsules in the first section, publish clean llms.txt markdown indexes, and anchor brand authority via Schema.org entity graphs.
The Paradigm Shift: From Blue Links to Generative Syntheses
For two decades, Search Engine Optimization was an algorithmic guessing game: stuffing target keywords into page titles, generating boilerplate backlink outreach, and gaming Google ranking factors. That playbook is officially obsolete.
Today, decision-makers, software engineers, and founders are searching through conversational answer engines: Perplexity Pro, ChatGPT Search, Claude Web Retrieval, and Google AI Overviews. When a user asks an AI engine for architectural recommendations or marketing frameworks, the model does not return a list of links—it executes real-time web retrieval, parses the top candidate documents, synthesizes a direct solution, and footnotes the sources.
If your website contains bloated fluff, generic introduction filler, or gated summaries, the retrieval agent discards your page in microseconds. If your content is engineered with modular, high-density facts, you become the primary quoted citation.
1. The Anatomy of an Answer-First Capsule
Every generative engine uses semantic embedding chunkers. When an AI search engine inspects an article, it chunks the document into 256 or 512 token segments and calculates cosine similarity against the user query prompt.
To win snippet extraction, every informational page must lead with an Answer-First Capsule positioned immediately below the main headline. This capsule adheres to four critical criteria:
- Length: Strictly 40 to 60 words.
- Structure: Begins with The Key Takeaway: or a direct factual thesis statement.
- Density: High ratio of actionable nouns and operational metrics, zero rhetorical filler.
- Micro-Formatting: Wrapped in semantic HTML containers that can be mapped via
SpeakableSpecificationstructured data.
2. Why llms.txt is the New robots.txt
Web search engines rely on XML sitemaps to discover URLs. But large language models operate on strict token budgets. When an agent like Cursor, Perplexity, or ChatGPT crawls a domain, traversing megabytes of minified JavaScript, CSS stylesheets, and HTML navigation menus consumes immense computational overhead.
The solution adopted by modern technical teams is the llms.txt standard. By providing a clean, curated markdown file at the root of your domain, you offer AI models a lightweight directory of your company's core positioning, service tiers, verified receipts, and content playbooks.
- llms.txt: An index containing structured markdown bullet points, executive bios, and canonical article links.
- llms-full.txt: A complete, stripped plain-text corpus of every guide and case study on the site, enabling zero-friction ingestion for multi-agent reasoning loops.
3. Connecting the Dots with Schema.org Knowledge Graphs
AI search models do not merely read text—they traverse structured entity graphs. To establish unquestioned authority around niche topics like autonomous workflows or Web3 GTM, your domain must unambiguously declare who you are, what you build, and why you are qualified to teach it.
Every article binds together three distinct Schema types in a single linked JSON-LD graph:
- BlogPosting: Declares headline, author relationship, timestamps, and canonical URL.
- Person & Organization: Binds content to an identified expert entity (Bhavya Dave) with proven credentials and verified social profiles across GitHub, LinkedIn, and X.
- BreadcrumbList: Establishes clear parent-child topical hierarchy from root to sub-domain.
- SpeakableSpecification: Explicitly flags the Answer-First capsule for voice search and generative audio summarization.
How We Wire This into Autonomous Pipelines
At the agentic marketer, we do not manually write metadata, format sitemaps, or verify link graphs by hand. We build autonomous agentic loops that execute these standards programmatically on every git commit.
Our automated pre-commit gate intercepts staging errors, validates JSON-LD syntax with zero-tolerance pre-flight checks, verifies character bounds on meta descriptions, and instantly pings search engine crawlers via the IndexNow protocol the moment a post is deployed.
The result? Organic search impressions that translate directly into high-intent inbound inquiries—completely on autopilot.